Appearance
After DSA: Two Routes for Optimizing the Indexer
After Sparse Attention, Why Is There Still a Quadratic Cost?
When I first looked at DSA, I had a natural question. Suppose a model faces a 128K-token context but ultimately lets each query read only 2K of those tokens. It appears to have skipped most of the history, so why does a new performance bottleneck still emerge at long context lengths? Looking one step earlier in the execution pipeline makes the answer straightforward: the model must first know which 2K tokens it should read, and “finding those 2K tokens” itself requires computation.
DeepSeek Sparse Attention (DSA) answers this problem by adding a lightweight indexer outside the main attention operation. The indexer first computes the relevance between the current query and every historical key, selects the top-
For the query at position
Here
This is much cheaper than running full attention directly, but it still contains one unavoidable operation: every query first scans all historical tokens. If the sequence length is
If the indexer's job is to help attention look at fewer tokens, can the indexer itself also look at fewer tokens?
I roughly organize the current work into two routes. The first accepts the basic form of the DSA indexer and then examines the dimensions along which its scores are redundant. The second takes a step back and rethinks how candidate addresses should be generated in the first place:
- Start from index-score patterns. Observe where the full index scores or top-
results are redundant, then make the existing indexer compute less, select less, or reuse existing results. - Start from the indexer architecture. Stop assuming that “a low-dimensional query performs one flat scan over all keys” is the only possible form, and redesign candidate generation, training supervision, and the system execution path.
Finding Redundancy in Score Patterns
We can first write the work of one indexer approximately as
: the number of layers that independently generate indices; : the indexer heads that participate in exact scoring; : the queries that must initiate retrieval separately; : the historical keys scanned by each retrieval.
Traditional DSA is almost “full” along all four dimensions: every layer recomputes the index, every head participates, every query retrieves independently, and every retrieval scans the complete history. Subsequent work did not immediately overturn the entire indexer. It first returned to actual routing maps to look for redundancy: are neighboring queries repeatedly selecting the same tokens, and are neighboring layers also repeating similar retrieval results? The two plots below provide an intuitive slice.
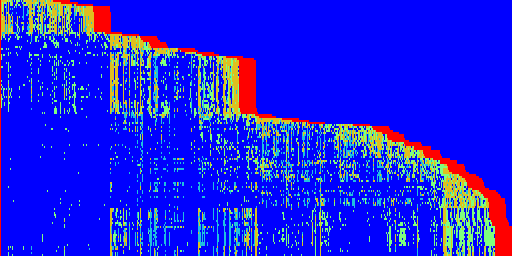
(a) Layer 23
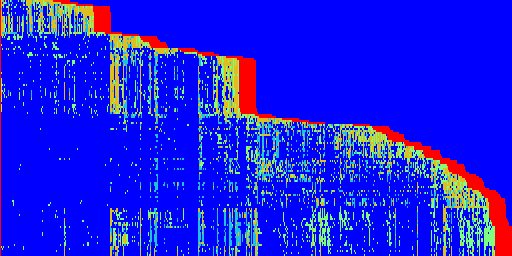
(b) Layer 18
The exact false-positive and false-negative positions are not identical in the two layers, but their overall structure is very similar. Neighboring queries often select similar tokens along contiguous regions, and different layers retain roughly the same routing skeleton. This observation cannot by itself prove which computations can safely be removed, but it provides a common starting point for subsequent work: if index patterns may repeat along the token, head, layer, and query dimensions, we can ask in turn which scores require exact computation and which searches can be coarsened, shared, or reused.
Token Axis: Not Every Token Needs an Exact Score
HISA: Efficient Hierarchical Indexing for Fine-Grained Sparse Attention observes that important tokens are often not scattered across history without any structure. Neighboring tokens exhibit some local consistency, so the model can first identify potentially important regions at a coarser block granularity and then perform the original token-level DSA scoring inside a small number of selected blocks.
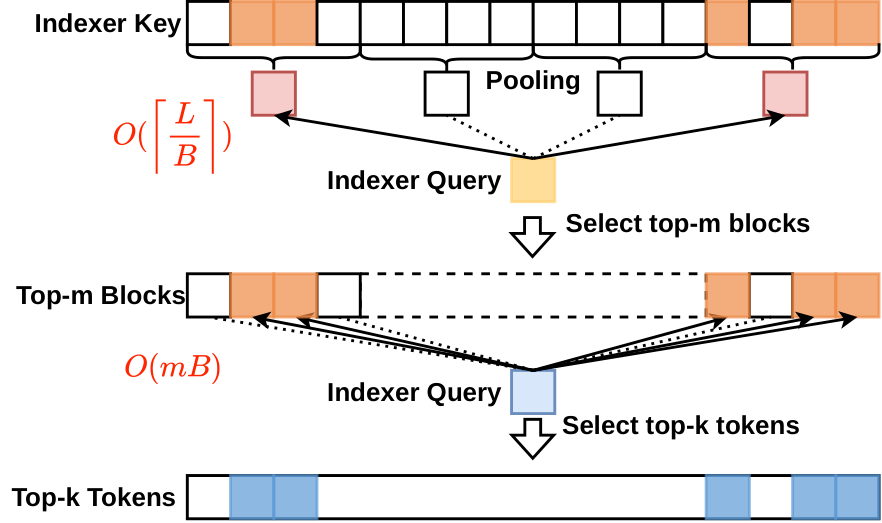
The figure can be read from top to bottom. The full set of indexing keys is first pooled into
It turns one flat search,
into
This can be understood as looking for one sentence in a library. The original indexer inspects the entire library page by page; HISA first uses a summary of each shelf to rule out most shelves, then checks the remaining shelves page by page. The key technique is not a vague switch to “block attention,” but making the block mean responsible only for candidate recall while returning final ranking to the original DSA token score. Concretely, HISA partitions indexing keys into fixed-size blocks of size
The benefit is that coarse screening can be cheap while precise screening does not waste the budget on an entire block. The paper's implementation also forcibly retains the first block and the last valid block, using deterministic rules to protect attention sinks, local context, and packed-sequence boundaries. Its irreversible risk is equally clear: if the block mean averages away a region with only one strong signal, the second stage can never see that token. HISA compresses
Head Axis: Not Every Indexer Head Is Equally Important
DSA uses multiple indexer heads because different low-dimensional subspaces may capture different relevance patterns. But “having many heads” does not imply that “every query must invoke every head.” The central observation of MISA: Mixture of Indexer Sparse Attention is that, for a particular query, only a small number of heads often determine the top-
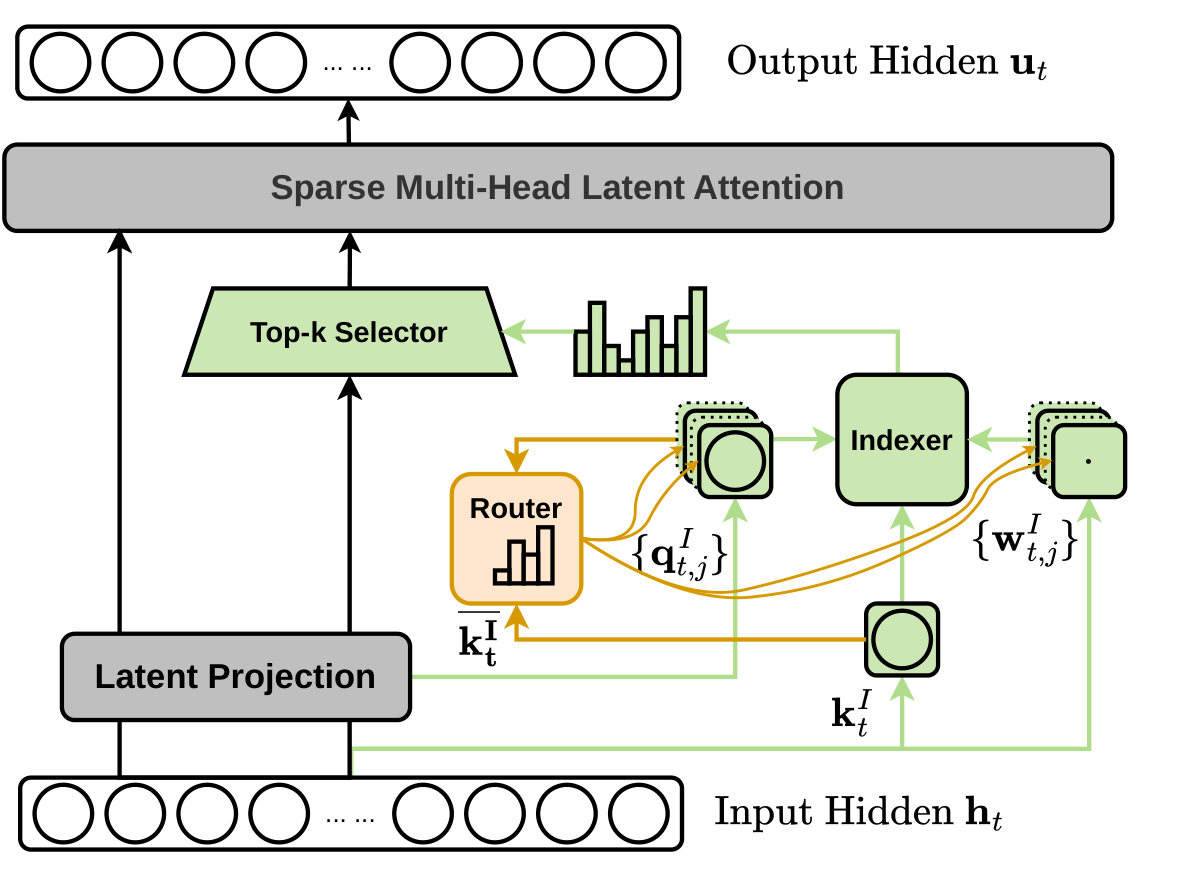
The green path in the figure is the original DSA indexer, while the orange Router is the lightweight branch added by MISA. The Router reads the indexer queries, their corresponding gates, and pooled indexing keys, then outputs an active-head mask. The following Top-
The crucial technique is that the head router cannot look only at the gate
The difference from HISA is clear:
- HISA retains all heads but reduces the number of tokens each head scans precisely;
- MISA retains the full token prefix but reduces the number of heads participating in exact scanning.
MISA therefore primarily reduces
Layer Axis: Neighboring Layers Need Not Find Addresses Again
IndexCache: Accelerating Sparse Attention via Cross-Layer Index Reuse observes that the top-
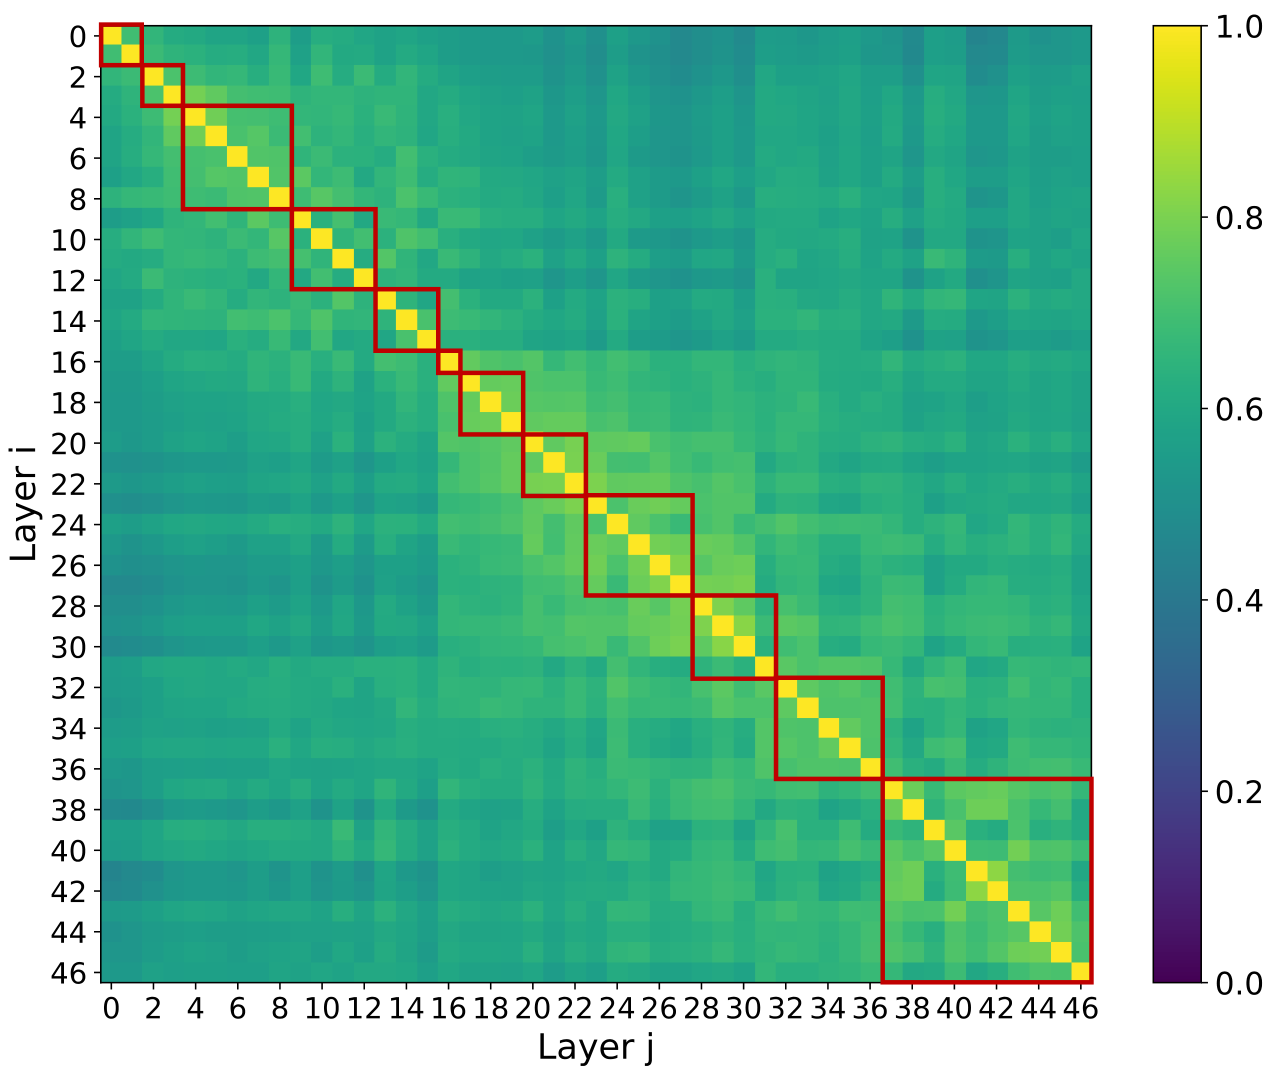
The IndexCache paper does not provide a separate Full/Shared execution diagram; this heatmap is the most important figure for understanding its structure. Both axes are layers, the color indicates top-
In my view, the most important IndexCache technique to explain is not reuse itself, but how the authors decide which layers can be removed. A seemingly natural solution is to compute the cosine similarity of neighboring layers' indices, attention outputs, or score vectors and merge the most similar layers. The paper does try such similarity proxies, but its final training-free method uses a greedy loss search that attempts to remove layers one at a time. Starting with every layer in Full mode, each step temporarily changes every candidate layer to Shared, evaluates the complete model on a fixed calibration set, and permanently removes the layer whose removal yields the lowest validation loss:
Here
Why not use cosine similarity? The paper explains that it measures only directional similarity and is insensitive to magnitude and a small number of high-scoring tokens, whereas a top-
Query Axis: Neighboring Queries Need Not Scan the Same Prefix Separately
PIVOT: Efficient Query-Group Indexing for Token-Level Sparse Attention turns to the query axis, which earlier work addressed less often. It finds that neighboring queries have highly overlapping top-
On the left, DSA performs a separate full scan for each of
There are then two ways to proceed:
- PIVOT-Reuse: the entire group directly shares the proxy's top-
; - PIVOT-Refine: the proxy first selects top-
candidates, then every query reranks them using the original DSA score.
PIVOT's key technique is to separate “sharing the scan” from “sharing the final selection.” The paper's ablation shows that mean pooling clearly outperforms using the first or last query in a group as the proxy; the mean better represents the common needs of the group. PIVOT-Reuse directly shares the proxy top-
A minimal example is four queries that respectively need
Redesigning the Indexer Architecture
The pattern route asks, “Which of the original scores need not be computed?” The architecture route goes further: “Why must we use a low-dimensional query to scan all keys flatly and then take a top-
Louver: Rewrite Top-
Sparse Attention as a Range Searching Problem (Louver) takes a very different entry point. Instead of directly asking “which
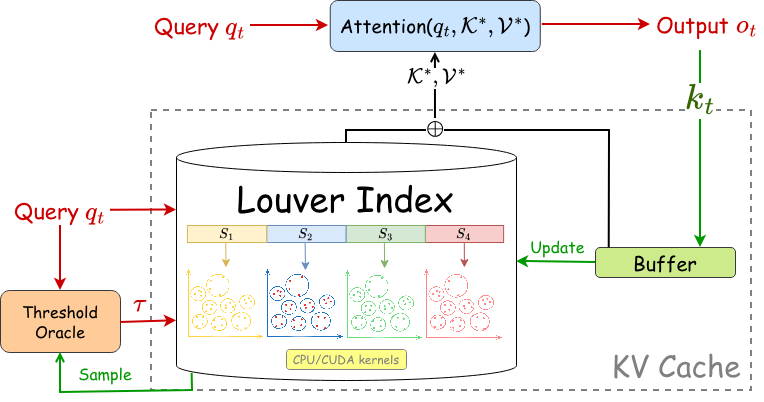
In the figure, one copy of the query enters the Louver Index, while another lets the Threshold Oracle estimate
It partitions keys into small clusters and stores a center
If a cluster's upper bound is below
The search can safely stop the first time
MiniMax Sparse Attention: Make the Indexer a Native GQA Branch
MiniMax Sparse Attention (MSA) does not directly adopt DSA's multi-head token top-
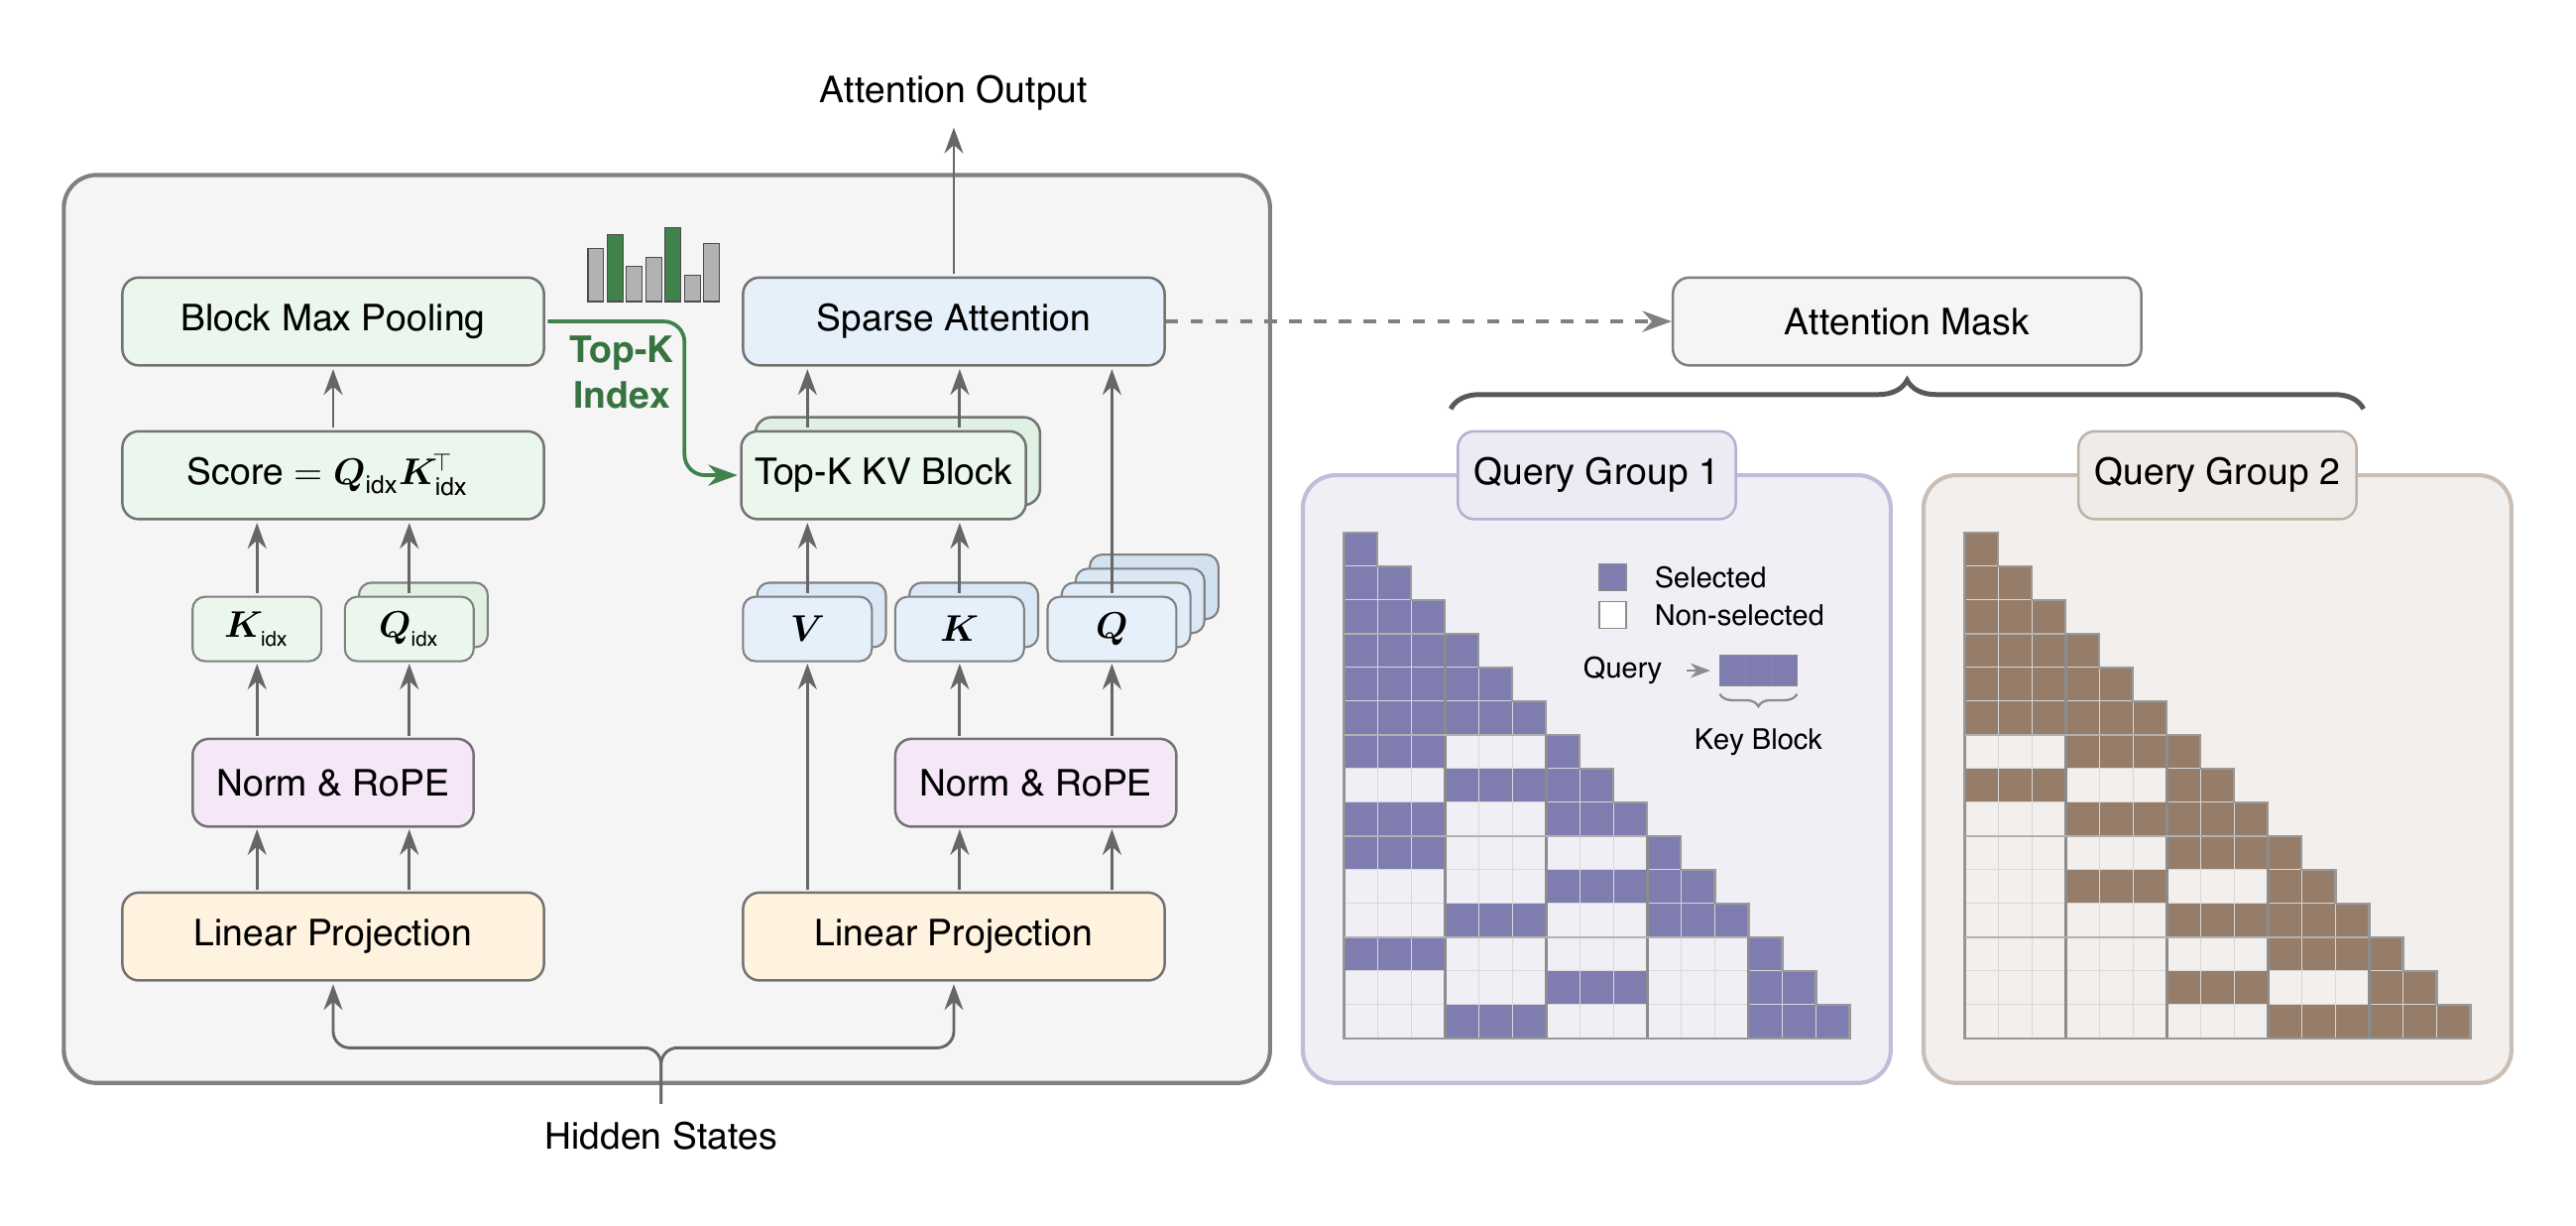
The left side clearly separates the two paths. The green Index Branch uses
- Per-GQA-group selection preserves retrieval differences between KV groups;
- block-level output provides contiguous KV access and better GPU compatibility;
- low-dimensional, shared index keys reduce the constant factor of the full scan.
The genuinely difficult and crucial technique is how to train a pure selector with a non-differentiable top-
MSA still contains a quadratic Index Branch, so it does not eliminate the full scan asymptotically. It uses low dimensionality, few heads, a shared index key, and regular block access to reduce the constant. It represents a different architectural approach: rather than optimizing an expensive token indexer after the fact, design the indexer interface, supervision, and kernel together during pretraining so that they are hardware-executable.
CLSA: Make Shared Routing Part of the Model Architecture
IndexCache searches for reusable indices in an ordinary layer-by-layer Transformer. You Only Index Once: Cross-Layer Sparse Attention with Shared Routing (CLSA) goes further. Built on YOCO's shared-KV architecture, it lets multiple cross-decoder layers read the same KV cache and generates only one common token route for those layers. Every cross layer still uses its own query to recompute attention weights over the selected tokens, but a common indexer decides “where to read.”
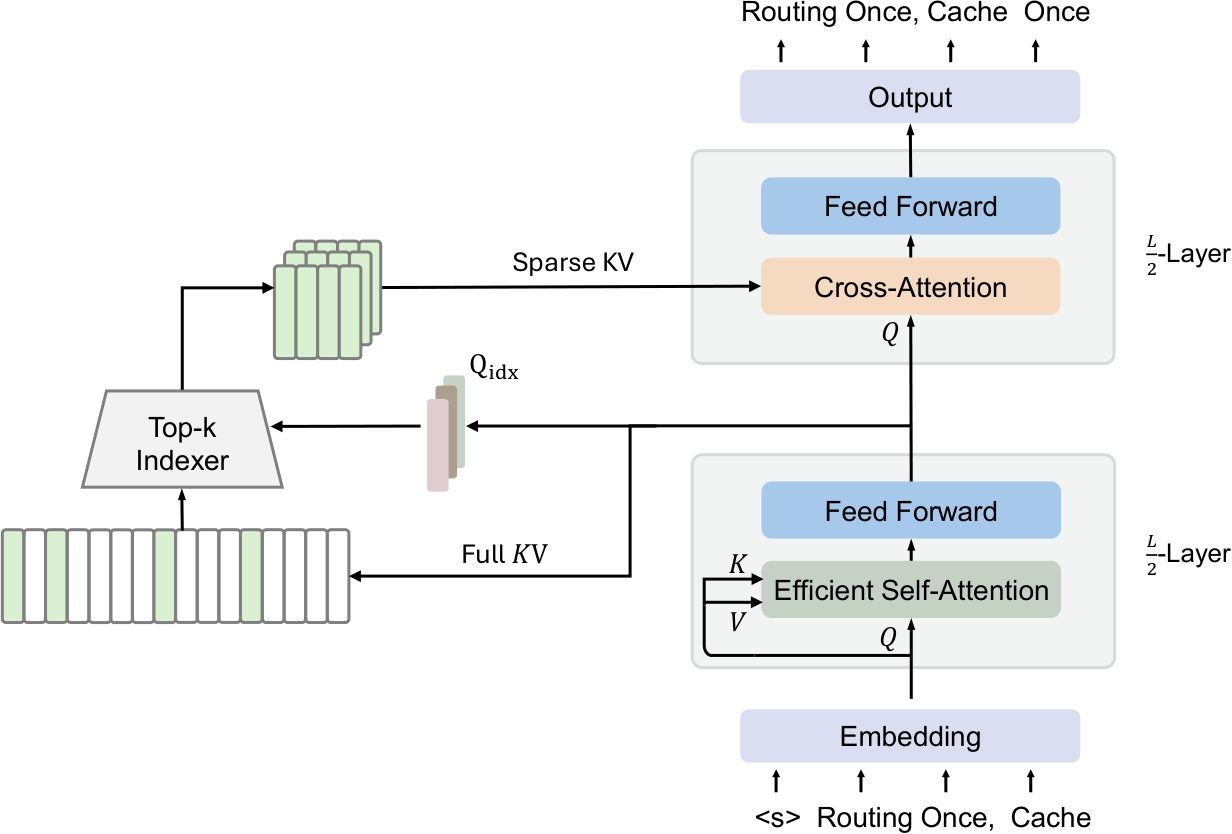
The lower half of the figure is the self-decoder, which produces Full KV only once. The common Top-
Its most important training technique is not making the shared indexer imitate an arbitrary single layer, but fitting it to the mean dense-attention distribution across all cross layers and attention heads:
If two layers concentrate most of their probability on tokens 1 and 3 respectively, the mean teacher asks the common route to cover both instead of favoring one anchor layer. Training first freezes the backbone and warms up only the indexer with KL, then jointly optimizes LM loss and distillation loss so that a random shared route does not damage the entire cross-decoder at the start. This turns layer-axis reuse from an empirical optimization into an architectural invariant. Instead of noticing that neighboring layers look similar and then attempting reuse, it first makes the layers share an information source and trains a route representing their common needs. The gain is more complete, but so is the cost: CLSA is not a drop-in patch for an existing DSA model. It requires a shared-KV backbone and large-scale training adaptation, and the mean teacher may dilute tokens that matter only to a few layers.
SparDA: Let the Indexer Work One Layer Ahead
SparDA: Sparse Decoupled Attention for Efficient Long-Context LLM Inference addresses not whether index results are repeated, but why selection must block attention. It adds a Forecast
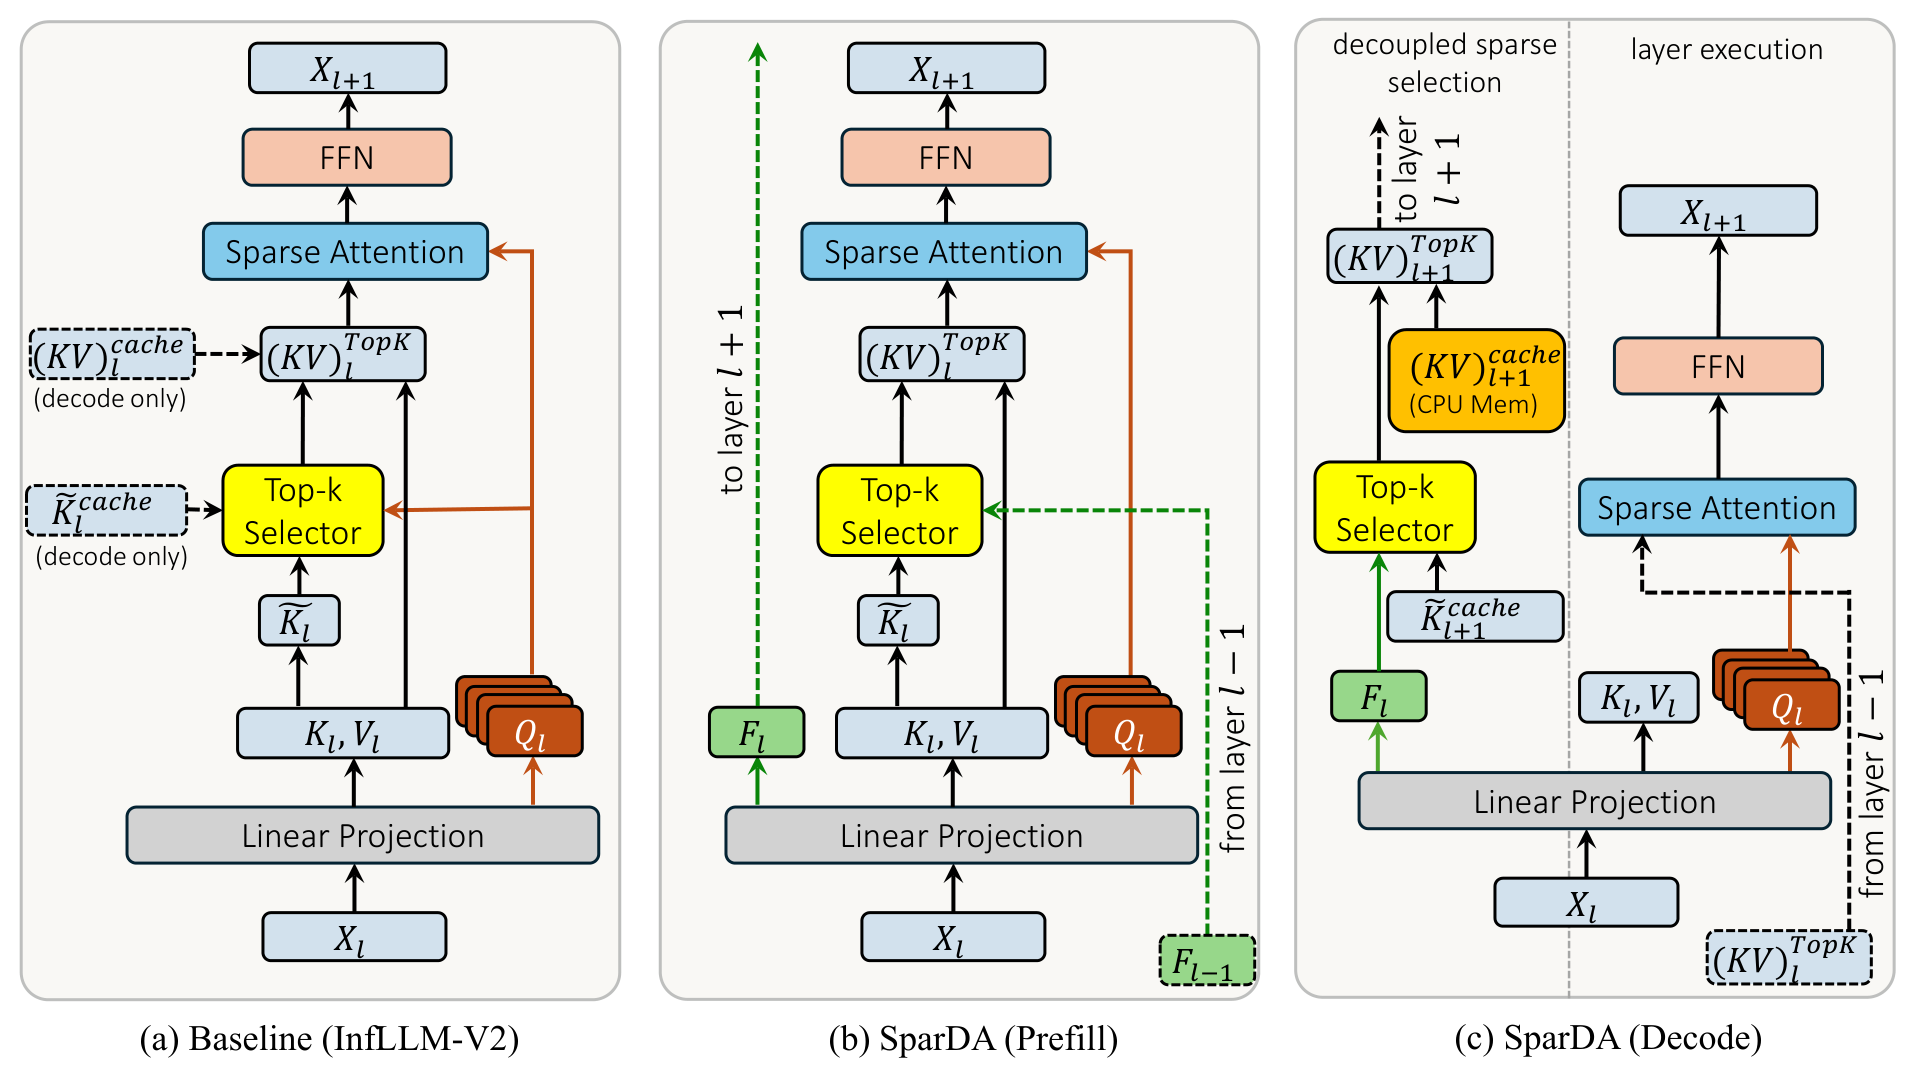
In panel (a), the baseline cannot select blocks until the current-layer
The actual attention at layer
SparDA redesigns the temporal position of the indexer: “select, transfer, then compute in the current layer” becomes “predict in the previous layer, overlapping selection and prefetching with current computation as much as possible.” This is why its benefit cannot be measured by FLOPs alone; shortening the critical path can matter more than reducing total work. It predicts the next layer's access addresses, not its KV content, and it requires training Forecast together with a specialized CPU–GPU offload pipeline. It therefore cannot be treated as a training-free scheduling trick.
References
- DeepSeek-AI. DeepSeek Sparse Attention / DeepSeek-V3.2.
- HISA: Efficient Hierarchical Indexing for Fine-Grained Sparse Attention. https://arxiv.org/abs/2603.28458
- IndexCache: Accelerating Sparse Attention via Cross-Layer Index Reuse. https://arxiv.org/abs/2603.12201
- MISA: Mixture of Indexer Sparse Attention for Long-Context LLM Inference. https://arxiv.org/abs/2605.07363
- PIVOT: Efficient Query-Group Indexing for Token-Level Sparse Attention. https://arxiv.org/abs/2607.24593
- Sparse Attention as a Range Searching Problem: Towards an Inference-Efficient Index for KV Cache. https://arxiv.org/abs/2605.06763
- MiniMax Sparse Attention. https://arxiv.org/abs/2606.13392
- Scout Before You Attend: Sketch-and-Walk Sparse Attention for Efficient LLM Inference. https://arxiv.org/abs/2602.07397
- You Only Index Once: Cross-Layer Sparse Attention with Shared Routing. https://arxiv.org/abs/2606.06467
- SparDA: Sparse Decoupled Attention for Efficient Long-Context LLM Inference. https://arxiv.org/abs/2606.04511